
The decision first
Best LLMs for resume writing at a glance
The best model is not automatically the newest or largest one. Before choosing, check whether it preserves facts, understands the target role, keeps the candidate’s voice, follows narrow editing instructions, and fits the required privacy and hardware boundaries.
Choose the model by resume task
| Resume task | Recommended model | Why | Watch out for |
|---|---|---|---|
| Refine selected bullets and summaries | Claude Sonnet 5.5 | A speed-and-cost-conscious starting point for repeated, focused edits | Fluent wording can still change the meaning or strengthen a claim |
| Tailor a resume and review it against a JD | GPT-6.1 Sol | Complex professional-work capabilities at lower token rates than Astra | Near-Astra general performance does not establish equal resume quality |
| Investigate unresolved evidence conflicts | GPT-6 Astra | An option for demanding reasoning when the initial review leaves specific issues unresolved | Higher token rates do not guarantee a better final resume |
| Organize mixed career documents | Gemini 3.8 Flash | PDF and multimodal input support an evidence-first preparation workflow | Long context is not unique, and extraction still needs source checks |
| Edit locally, including multilingual drafts | Qwen3.5-9B | Downloadable weights support a locally configured editing workflow | Hardware, quantization and language affect results |
| Run a structured local audit | gpt-oss-20b | Configurable reasoning and structured outputs support categorized checks | Text-only input cannot assess visual page layout |
Claude Sonnet 5.5
A speed-and-cost-conscious starting point for repeated, focused edits
Watch out: Fluent wording can still change the meaning or strengthen a claimGPT-6.1 Sol
Complex professional-work capabilities at lower token rates than Astra
Watch out: Near-Astra general performance does not establish equal resume qualityGPT-6 Astra
An option for demanding reasoning when the initial review leaves specific issues unresolved
Watch out: Higher token rates do not guarantee a better final resumeGemini 3.8 Flash
PDF and multimodal input support an evidence-first preparation workflow
Watch out: Long context is not unique, and extraction still needs source checksQwen3.5-9B
Downloadable weights support a locally configured editing workflow
Watch out: Hardware, quantization and language affect resultsgpt-oss-20b
Configurable reasoning and structured outputs support categorized checks
Watch out: Text-only input cannot assess visual page layoutSee how your draft matches the role. Add your resume and target job description in InterviewCue to review role match, evidence gaps and interview-preparation priorities.
Check Your Resume Against a Job DescriptionChoosing a writing model is only one part of a complete software engineer interview preparation framework. Use the task table to separate work that belongs in the resume stage from evidence that should be developed through interview practice.
The Claude choice
Which Claude Model Is Best for Resume Writing?
Start with Claude Sonnet 5.5 for focused bullet edits, concise summaries, and repeated revisions where speed and cost matter. Consider Opus 5.5 when you need to reconcile conflicting career notes or decide which evidence supports a target role. Its documented focus on knowledge and professional work makes it a candidate for that workflow, not a proven resume-writing winner. Haiku 5.5 is an option for narrow extraction and classification tasks. Review every changed claim.
The comparison rubric
What to look for in an LLM for resume writing
A useful resume model must do more than produce polished sentences. These five dimensions separate a dependable editing workflow from a fluent but risky rewrite.
Factual control
Dates, titles, metrics, tools, scope, and ownership remain tied to the supplied evidence.
The model invents, changes, or silently strengthens a claim.
Job relevance
Verified experience is connected with the target role and its most important requirements.
Keywords are inserted where the resume contains no supporting evidence.
Editing judgment
Bullets become clearer, more specific, and more natural without losing the candidate’s voice.
The output becomes generic, inflated, repetitive, or semantically weaker.
Instruction control
The model returns the requested format and edits only the requested section.
It rewrites the whole resume, ignores the schema, or hides uncertainty.
Practical fit
Privacy, access, cost, speed, and hardware requirements fit the candidate’s workflow.
The model is too difficult, expensive, or risky to use consistently.
Job relevance should come from evidence the candidate can explain, not copied keywords. The behavioral interview preparation guide is a useful next check: every highlighted achievement should support a clear story about the situation, decision, action, and result.
The same work for every model
Three shared tasks for a fair resume-writing comparison
Suggested comparison method, not completed testing: give the models you are considering the same sanitized resume, fact ledger, target job description, prompts and output format. No scored runs or public output samples support the recommendations in this article.
Fact-constrained bullet rewrite
Three weak bullets, a verified fact ledger, and target-role context.
Original and revised bullets, evidence used, and claims to confirm.
Resume-to-job evidence-gap analysis
One sanitized master resume and one target job description.
A supported, partial, or unsupported requirement matrix with citations.
Seeded final-resume audit
One targeted resume with seeded date, metric, title, and claim errors.
A prioritized issue list with the line, error, conflict, and action.
Record the exact model ID, date, access surface, reasoning setting, token cost and elapsed time. Reject invented facts before comparing prose. InterviewCue’s separate resume report is not a model in this shortlist.
The full shortlist
Six cloud and local LLMs compared
These are starting points for particular tasks, with overlapping editing and analysis capabilities. Review the workflow and limitation together.
Claude Sonnet 5.5
Best forSelected bullet rewrites, concise summaries and wording revisions
Anthropic positions Sonnet 5.5 around speed and intelligence, with standard API rates of $2 per million input tokens and $10 per million output tokens—half the listed rates of Opus 5.5. That makes it a practical starting point for repeated edits to small sections. Supply verified facts and a writing sample, then ask for each revision alongside its supporting evidence.
Access: Use the Claude API with claude-sonnet-5-5. For the Claude app, check your account’s model picker and usage limits; API pricing is separate from app subscription costs.
GPT-6.1 Sol
Best forJD evidence mapping, targeted revisions and multi-step checks
OpenAI describes GPT-6.1 Sol as delivering near-Astra performance on complex professional work at a lower cost. Use it to map job requirements to verified experience, revise selected bullets, and check the result against your source notes. Standard API rates are $2 per million input tokens and $10 per million output tokens for prompts up to 272K input tokens. This supports trying Sol before Astra, without assuming equal resume-writing quality.
Access: API model ID: gpt-6.1-sol. API use requires eligible access and separate billing. Availability in ChatGPT or Codex depends on the product and account.
Gemini 3.8 Flash
Best forBuilding an evidence inventory from PDFs, career notes and job descriptions
Gemini 3.8 Flash supports PDF, text, image, audio and video input, along with structured outputs. Use it to organize supplied career documents into a source-linked evidence inventory before rewriting. Ask for the document and passage supporting each achievement, and flag missing or conflicting details. Its large input capacity is useful, but long context is also available in current GPT and Claude models.
Access: Use Google AI Studio or the Gemini API with gemini-3.8-flash, subject to account and regional availability. Check the selected model rather than assuming a consumer-app label identifies the API version.
Qwen3.5-9B
Best forPrivate editing and multilingual drafts
The official Qwen model card provides downloadable weights, multilingual support and compatible inference tools. We recommend it for constrained local edits when the operator can configure a supported runner and check the final wording. Local privacy depends on the complete setup, as explained below.
Access: Download Qwen/Qwen3.5-9B from the official model repository; choose a compatible local runtime and weight format. Hosted inference is a separate data-processing choice.
gpt-oss-20b
Best forDate, title and claim consistency checks
OpenAI documents open weights, configurable reasoning and structured outputs. Our proposed use is a second-pass audit with fixed issue categories and source citations, using a runner that supports the required harmony format.
Access: Download openai/gpt-oss-20b or use a compatible local app such as LM Studio or Ollama. Open weights do not mean that this model is served by the OpenAI hosted API.
GPT-6 Astra
Best forConflicting career evidence and difficult relevance decisions
GPT-6 Astra remains OpenAI’s highest-capability option for demanding reasoning and professional work. Consider it when a Sol review leaves specific problems unresolved, such as conflicting project notes, unclear ownership or difficult tradeoffs about which experience to emphasize. Its role here is an escalation option for a defined problem, rather than a required final step for every resume.
Access: API model ID: gpt-6-astra. API billing and access are separate from ChatGPT and Codex availability.
API, Codex and ChatGPT are different entry points. A ChatGPT subscription does not cover API charges. When choosing the best resume GPT for your workflow, confirm your account’s model picker, upload limits and billing. OpenAI’s model-selection guide describes API choices; product availability depends on the account.
Match the model to the work
How to Choose an LLM for Your Resume Workflow
Choose a starting point by the work you need to finish: Sonnet 5.5 for focused, repeated edits; GPT-6.1 Sol for JD-based tailoring and review; or a local model when document processing must stay on your device. These are workflow recommendations, not exclusive capabilities—both Claude and GPT can support editing and analysis.
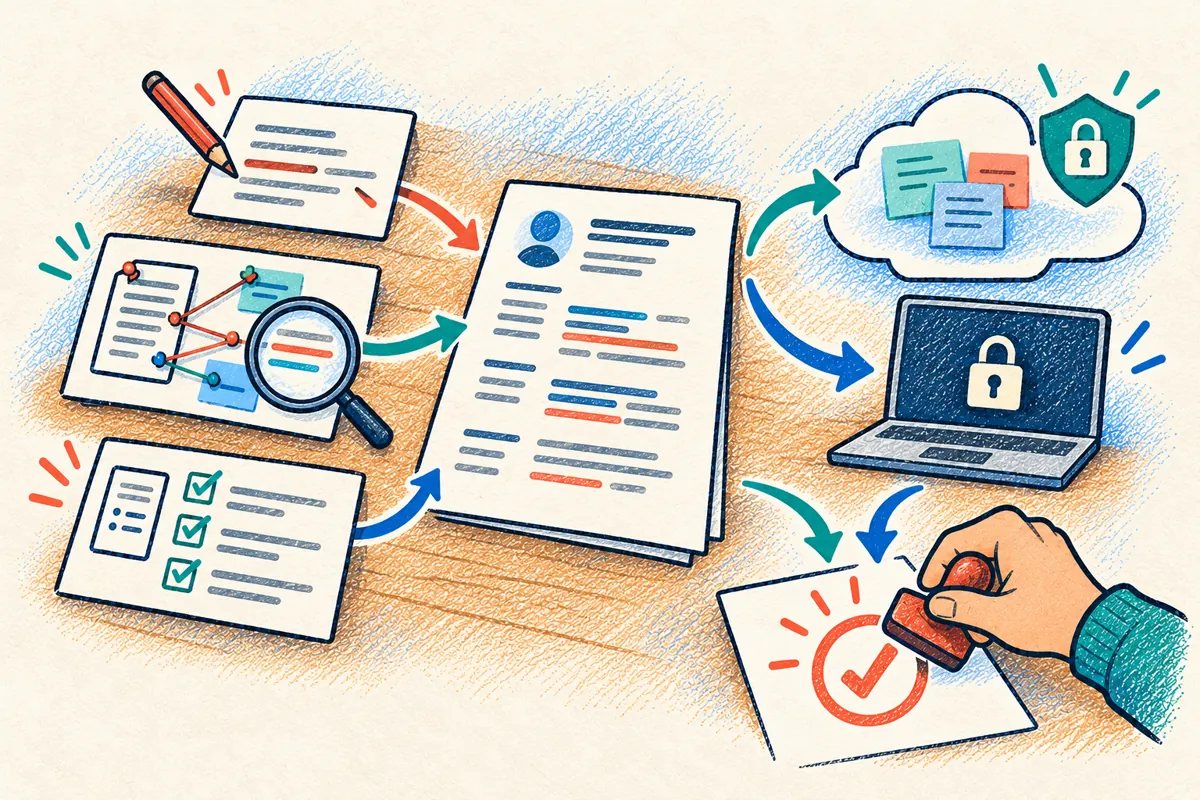
Choose the workflow before the model
Polish a few supported bullets → narrow edit. Tailor to a job description → map requirements to evidence first. Audit a draft → list claims and source lines.
Yes → request a rewrite with a source note per claim. No → collect the missing dates, actions, or outcomes before writing.
Cloud allowed → sanitize inputs and review provider controls. Must stay on device → use an offline local workflow, including parsing and logs.
Resume Tailoring and Job Applications
GPT-6.1 Sol is our cost-conscious starting point for mapping a job description to verified experience, revising selected bullets and checking consistency across application materials. Consider GPT-6 Astra or Claude Opus 5.5 if conflicting evidence or difficult relevance decisions remain unresolved. Tailoring should improve emphasis and clarity without adding unsupported skills, responsibilities or keywords. See the step-by-step resume tailoring guide for the full process.
Best Local LLM for Resume Writing
The best local AI model for resume work depends on your hardware and editing needs. Qwen3.5-9B is our local starting point for constrained editing and multilingual drafts; gpt-oss-20b is our alternative for structured consistency checks. Hardware needs depend on the runner, quantization and context size: LM Studio recommends at least 16 GB RAM and 4 GB dedicated VRAM on Windows, while the official gpt-oss-20b card says its MXFP4 configuration can run within 16 GB of memory. Neither figure guarantees smooth performance for every model or context. Local processing improves privacy only when inference, document parsing, embeddings and logs remain local.
A fact-safe system
Use the LLM in four controlled passes
Build the evidence base
Start with a master resume, achievement notes, and one target job description. The model should never be the source of a claim.
Map requirements before writing
Classify each job requirement as supported, partially supported, or unsupported. Missing evidence becomes a question, not an invented bullet.
Rewrite in small batches
Edit three to five bullets at a time and request the original, revision, source evidence, and reason for every change.
Audit the submitted version
Check dates, titles, metrics, links, tense, role terminology, page breaks, and whether the candidate can defend every retained claim.
For a guided second pass, use the AI resume checker for job-match gaps. It compares the resume with the target role and turns the findings into clearer interview-preparation priorities.
Once the resume is grounded in verified evidence, turn the strongest bullets into interview stories with the resume-to-interview answer framework. Then practice handling interview follow-up questions so dates, decisions, scope, and results remain consistent when an interviewer probes deeper.
Ready to use
Copyable prompts for a safer resume workflow
When choosing the best AI resume writer for your workflow, keep prompts short enough to inspect why the model changed the document.
Job-match analysis
Compare the target job description with my master resume. Return a table with: requirement, importance, verified resume evidence, evidence gap, and recommended action.

Classify every item as supported, partially supported, or unsupported. Do not rewrite the resume yet and do not infer missing experience.Fact-safe bullet rewrite
Rewrite only the selected bullets. Preserve the original meaning, lead with a clear action, include a verified result when available, and use target-role terminology only when it accurately describes the work.

Return: original bullet, revised bullet, source evidence used, and any claim requiring confirmation.Final resume audit
Audit the targeted resume against the master resume and job description. Flag unsupported claims, changed dates or titles, repeated verbs, vague bullets, missing role requirements, inconsistent tense, and wording that sounds inflated.

Do not rewrite automatically. Return a prioritized issue list with the exact line that needs review.
Common decisions
Frequently asked questions
Which LLM is best for resume writing?
Start with Sonnet 5.5 for focused editing or GPT-6.1 Sol for JD-based tailoring and review. Consider Opus 5.5 or Astra for unresolved, demanding work. Gemini 3.8 Flash helps organize mixed documents; Qwen3.5-9B and gpt-oss-20b cover local workflows. These are task-based choices, not an overall winner.
Which Claude model is best for resume writing?
Sonnet 5.5 is our speed-and-cost-conscious starting point for focused revisions. Consider Opus 5.5 for conflicting source material or difficult evidence-selection decisions. Haiku 5.5 can handle narrow extraction and classification. These are suggested uses, not measured resume rankings.
Is GPT-6 Astra better than GPT-6.1 Sol for resumes?
That has not been established here. OpenAI describes Sol as offering near-Astra performance on complex work at lower token rates. Start with Sol when cost matters, and consider Astra if specific issues remain unresolved. Judge the additional review by whether it improves the result.
Which is the best LLM for CV writing?
For a professional CV, Sonnet 5.5 and GPT-6.1 Sol are practical starting points for focused editing and role tailoring. For an academic CV, preserve the full publication, teaching, grant and research record; use the model to organize supplied information, not invent or verify citations.
What is the best local LLM for resume writing?
Qwen3.5-9B is our local editing starting point; gpt-oss-20b is an alternative for structured audits. Both need compatible hardware and a configured runner. Local privacy requires local inference and document processing without cloud tools or remote logging.
What is the best LLM for job applications?
GPT-6.1 Sol is our starting point for mapping a JD to verified experience and keeping application materials consistent. Sonnet 5.5 is an alternative for focused revisions. Consider Opus 5.5 or Astra when specific evidence conflicts remain unresolved, and check the final application yourself.
Can an LLM make a resume ATS-friendly?
An LLM can compare terminology with a job description, simplify headings and flag unclear content. It cannot guarantee how an employer’s ATS will parse or rank the final file. Review formatting and every keyword yourself; no ATS pass rate is claimed here.
Write a resume you can defend
Conclusion: which LLM is best for resume writing?
Start with Claude Sonnet 5.5 for focused edits or GPT-6.1 Sol for cost-conscious tailoring and review. Consider Opus 5.5 or GPT-6 Astra when a specific evidence or reasoning problem remains unresolved. Gemini 3.8 Flash supports mixed-document preparation; Qwen3.5-9B and gpt-oss-20b remain our local editing and audit options.
Choose the best LLM for resume writing by task, budget and data requirements. Keep claims tied to verified experience, revise in small batches, and check the exported resume before submitting it. When the application is ready, use AI mock interview practice to test whether the same evidence is clear when spoken aloud. If you prefer a guided way to compare your resume with a target role, InterviewCue also offers a Resume Optimizer whose report can serve as a starting point for your own final review.
See how your draft matches the role. Add your resume and target job description in InterviewCue to review role match, evidence gaps and interview-preparation priorities.
Check Your Resume Against a Job Description